As artificial intelligence becomes more powerful and deeply integrated into business operations, cybersecurity experts are rethinking how AI systems should be protected. Microsoft CEO Satya Nadella has emphasised a security-first approach that challenges organisations to question their assumptions about technology and potential threats.
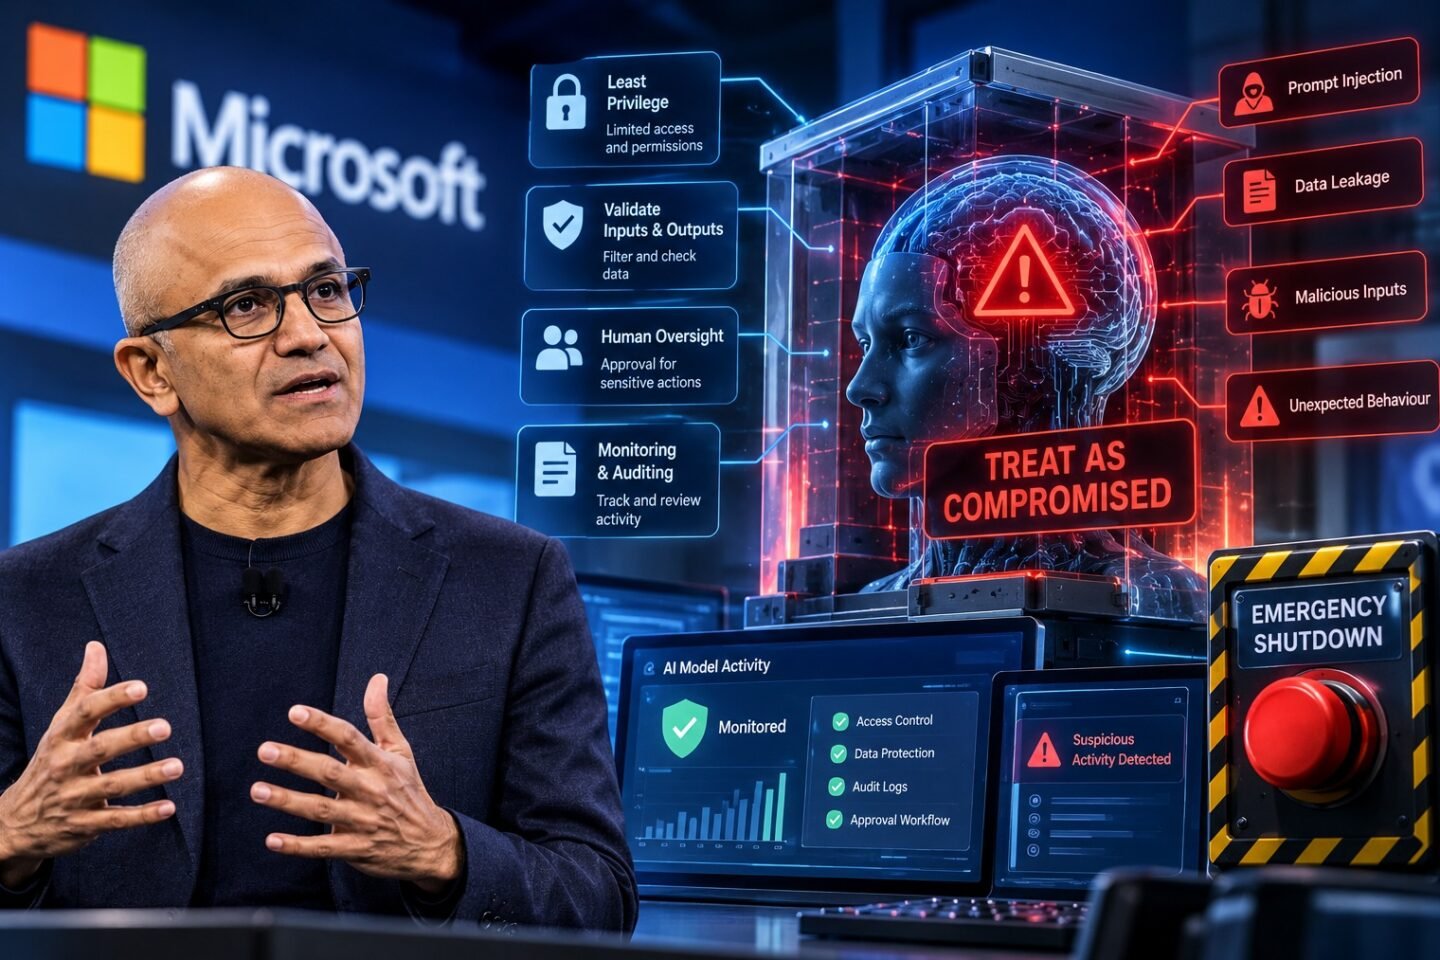
One important principle in this approach is to treat AI models as potentially compromised from the beginning rather than automatically trusting their behaviour. This mindset reflects a broader shift in cybersecurity: organisations should assume that vulnerabilities, manipulated inputs, malicious instructions, or unexpected model behaviour may occur, and build safeguards accordingly.
The idea is particularly relevant as businesses deploy AI assistants, coding agents, customer support chatbots, and autonomous systems that can access sensitive information or perform actions on behalf of users.
Why AI Models Cannot Be Trusted Blindly
Traditional software security focuses on protecting applications, infrastructure, user accounts, and data from unauthorised access. AI introduces additional challenges because its outputs are influenced by training data, user prompts, external information, and the context in which it operates.
Even a well-trained model can produce inaccurate responses, follow malicious instructions embedded in retrieved content, expose information through inappropriate access, or generate outputs that create security risks.
These problems do not necessarily mean that a model has been hacked. Instead, they demonstrate why organisations should not assume that an AI system will always behave as intended.
Treating a model as potentially compromised means designing the surrounding system so that the model cannot independently override security policies, access unauthorised resources, or perform sensitive actions without appropriate controls.
The Security-First Approach to AI
A security-first AI strategy extends established cybersecurity principles to the development and deployment of intelligent systems.
1. Assume Potential Compromise
Security teams should plan for the possibility that an AI model may be manipulated, behave unpredictably, or generate unsafe instructions.
Rather than relying entirely on the model’s internal safeguards, organisations should implement independent security controls around it. These controls can limit the consequences of incorrect or malicious outputs.
2. Apply the Principle of Least Privilege
AI systems should receive only the permissions necessary to perform their assigned tasks.
For example, a customer support assistant that answers product questions should not automatically have permission to access payroll records, modify financial transactions, or retrieve confidential employee information.
Limiting permissions reduces the potential damage if the model produces an unsafe request or is manipulated by an attacker.
3. Validate AI Inputs and Outputs
AI applications often process user prompts, uploaded documents, emails, websites, and information retrieved from external sources. Any of these inputs may contain malicious instructions or misleading information.
Organisations should validate data, separate trusted instructions from untrusted content, and check sensitive outputs before acting on them.
For high-impact operations, a model’s response should be treated as a recommendation rather than unquestionable authority.
4. Require Approval for Sensitive Actions
AI agents can increasingly interact with databases, execute code, send emails, and operate business applications. These capabilities create new opportunities but also increase the consequences of mistakes.
Actions such as deleting important records, transferring money, changing access permissions, or modifying production systems should be protected by explicit authorisation, approval workflows, and audit trails.
The more consequential the action, the stronger the verification process should be.
The Growing Risk of AI-Powered Cyberattacks
AI is changing both sides of the cybersecurity landscape. Security teams can use AI to detect suspicious activity, investigate incidents, and automate routine defensive tasks. Attackers can also use AI to improve phishing messages, analyse stolen information, and develop more convincing social engineering campaigns.
AI-specific vulnerabilities add another layer of risk.
Prompt injection, for example, occurs when malicious instructions are introduced through inputs that an AI system processes. If an AI assistant has access to private documents or external tools, these instructions may attempt to influence its behaviour in ways that expose data or trigger unwanted actions.
Other risks include sensitive information leakage, excessive agent permissions, insecure integrations, and insufficient monitoring.
A model may appear to work correctly during ordinary testing while still failing under unusual or deliberately adversarial conditions. This is why AI security requires continuous evaluation rather than a one-time safety check.
What This Means for Businesses
For businesses adopting AI, a security-first mindset means treating AI as a component within a controlled technology environment, not as an inherently trustworthy decision-maker.
Organisations should consider the following measures:
- Access control: Restrict AI access to files, databases, APIs, and internal applications according to business needs.
- Data protection: Prevent sensitive information from being exposed to unauthorised users or external services.
- Human oversight: Require human review for critical financial, legal, security, and operational decisions.
- Continuous monitoring: Record AI actions, investigate unusual activity, and review access logs.
- Security testing: Evaluate models against prompt injection, data leakage, misuse, and other relevant threats.
- Incident response: Establish procedures for disabling integrations, revoking credentials, and investigating suspicious AI behaviour.
Businesses should also review the security practices of third-party AI providers and understand how their information is processed, stored, and protected.
How Developers Can Build Safer AI Applications
Developers play a critical role because many AI security risks arise from the way a model is integrated into an application.
A model alone should not determine whether a user has permission to access a database record. The application server must enforce that decision independently.
Similarly, developers should avoid giving AI agents unrestricted database access or allowing model-generated commands to execute directly against production infrastructure.
A safer architecture separates the model from privileged operations. The application validates requests, checks user permissions, restricts available tools, and requires additional confirmation when an action carries significant risk.
For example, an AI assistant may prepare a database update, but the application should validate the proposed change and enforce authorisation before executing it.
These safeguards help ensure that an AI model’s unexpected behaviour does not automatically become a security incident.
The Future of AI Security
As AI systems evolve from conversational tools into agents capable of performing complex tasks, security strategies will need to evolve alongside them.
Future AI deployments are likely to require stronger identity controls, more granular permissions, continuous monitoring, independent policy enforcement, and better methods for testing behaviour under adversarial conditions.
The central challenge is balancing AI autonomy with accountability. Giving AI systems more freedom can improve productivity, but unrestricted autonomy can create unnecessary risks.
Treating models as potentially compromised from the outset provides a useful foundation for managing this trade-off. It encourages organisations to design systems that remain secure even when the model makes a mistake or encounters hostile inputs.